
AssemblyAI LLM Gateway Review 2026: 57 Models, Sync API Price Cut to $0.30/hr and Real Limits
AssemblyAI LLM Gateway now routes 57 models through one OpenAI-compatible endpoint at provider rates with automatic fallbacks and native speech-to-text integration.
AssemblyAI LLM Gateway routes requests to 57 models through a single OpenAI-compatible endpoint at the provider's listed rates with no markup. The October 25, 2026 update added 20 models including NVIDIA Nemotron variants, GLM-5.3 Flash, DeepSeek V4.1 Flash, GPT-6 Sol variants, Sonnet 5.5, Gemini 4 Argon, Grok 4.7, and Opus 5.5. The Sync Speech-to-Text API price fell to $0.30 per audio hour, below the realtime streaming rate but above the async option.
Model Selection and Core Features
The gateway supports tool calling, structured outputs, streaming, and prompt caching on compatible models. It maintains separate US and EU endpoints, with EU data residency available for selected providers. New hosts include Digital Ocean and Inception Labs in addition to AWS Bedrock, Vertex, and Fireworks. Zero data retention can be enabled per request.
Integration with AssemblyAI speech-to-text uses the same API key, eliminating an extra network hop when building voice pipelines. The service supplies Voice Standard Bench scores that compare quality, speed, and cost across real transcripts and task types. Rate limits stand at 30 requests per minute per model on paid accounts. The free tier covers speech-to-text usage but excludes LLM Gateway tokens.
Automatic per-request fallbacks activate when a provider returns an error or timeout. Global routing incurs no surcharge; US and EU in-region routing adds 10 percent. Volume discounts require direct sales contact for high-usage accounts.
AssemblyAI Pricing 2026 and Sync API Changes
LLM Gateway charges appear on a separate line and are never offset by free-tier credits. Input and output rates vary by model. Nemotron Lightning 3.5 lists at $0.05 input and $0.20 output per million tokens. Mid-tier models range from $0.10 to $2.00 input. Frontier models such as GPT-6 Sol, Sonnet 5.5, Gemini 4 Argon, and Grok 4.7 carry $2.00 input and $6–10 output. Opus 5.5 reaches $4.00 input and $20 output.
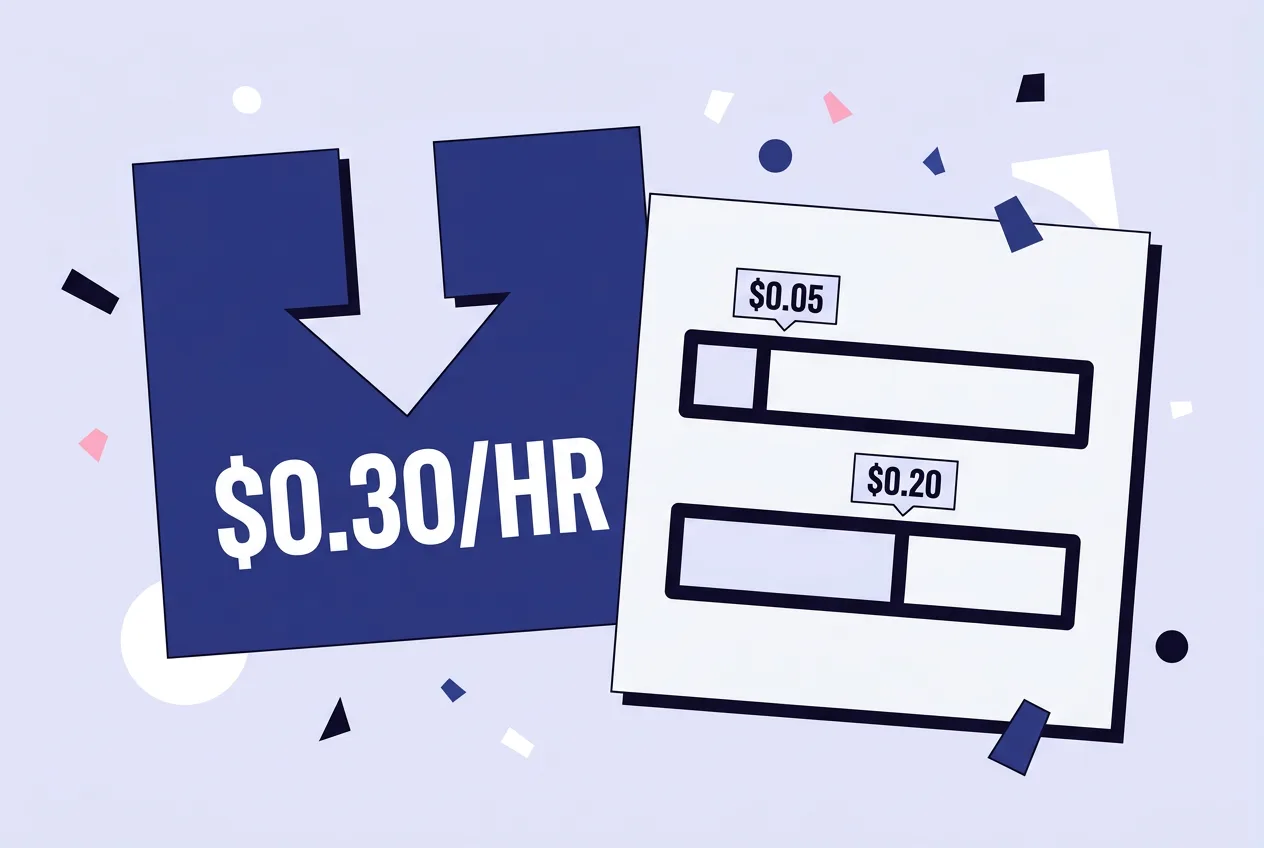
The Sync API price reduction of approximately 33 percent to $0.30 per audio hour applies to single-request finished transcripts for short clips. This rate sits 43 percent above the async Universal-3.5 Pro price of $0.21 per hour yet remains below the Universal-3.6 Pro realtime streaming rate of $0.45 per hour. Speech-to-text usage continues to draw from free-tier credits, while LLM Gateway usage does not.
| Model | Input per 1M tokens | Output per 1M tokens |
|---|---|---|
| Nemotron Lightning 3.5 | $0.05 | $0.20 |
| Qwen3.5 4B Fast | $0.10 | $0.50 |
| GPT-6 Sol / Sonnet 5.5 | $2.00 | $6–10 |
| Opus 5.5 | $4.00 | $20 |
Practical Limits and Comparison Points
Paid accounts face the 30 requests-per-minute cap per model. Prompt caching and structured outputs reduce effective cost only when the target model supports them. EU routing adds the 10 percent surcharge even when latency is acceptable. Users building high-volume voice agents should test fallback behavior and benchmark specific models on their own transcripts before committing traffic.
Compared with general routers such as OpenRouter, AssemblyAI LLM Gateway provides tighter coupling to its own speech-to-text output and supplies task-specific voice benchmarks that the broader platforms lack. It does not replace dedicated speech-to-text services for long-form transcription, where the async tier remains cheaper. No further immediate price changes have been announced beyond the October 25 adjustments.
Frequently asked questions
Does AssemblyAI LLM Gateway add any markup to model prices?
No. The service routes at the provider's published rates with zero markup on global traffic. US and EU in-region routing carries a 10 percent surcharge.
What changed with the Sync Speech-to-Text API on October 25, 2026?
The price dropped to $0.30 per audio hour. The endpoint now returns a finished transcript for short clips without polling or WebSocket connections.
Are free-tier credits usable for LLM Gateway requests?
Free-tier credits apply only to speech-to-text usage. LLM Gateway token consumption is billed separately regardless of account tier.
How many models does the gateway currently support?
The October 25 update brought the total to 57 models. Additions included multiple Nemotron, GLM, DeepSeek, GPT-6, and Claude variants.
Comments 7